Term
Mixture of Experts (MoE).
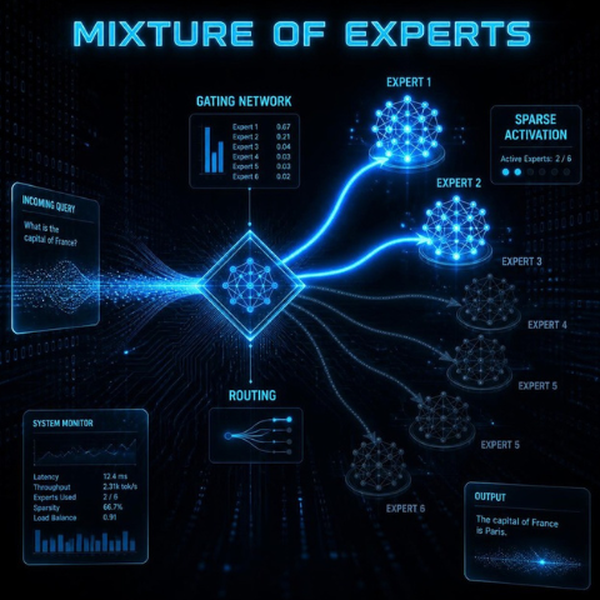
A machine learning architecture where multiple specialized sub-networks (experts) are trained, and a gating mechanism routes each input only to the most relevant experts.
Mixture of Experts (MoE) is a neural network design that significantly increases a model's capacity without a proportional increase in computational cost. Instead of activating the entire network for every task, MoE routes inputs to a select few "expert" layers that specialize in specific types of data or queries. This sparse activation allows for massive, highly capable models that are faster and cheaper to run than traditional dense models.